Microservices vs Monolith Architecture Pros and Cons Explained for Scalable Systems
Scaling a system is not only about handling more requests. It is about organizing code, data, and teams so that change remains safe and fast. In software development, the most common architectural choice is between a monolith and microservices. This guide explains the trade-offs for scalable systems and helps you choose with clear criteria instead of hype.
What a monolith and microservices are
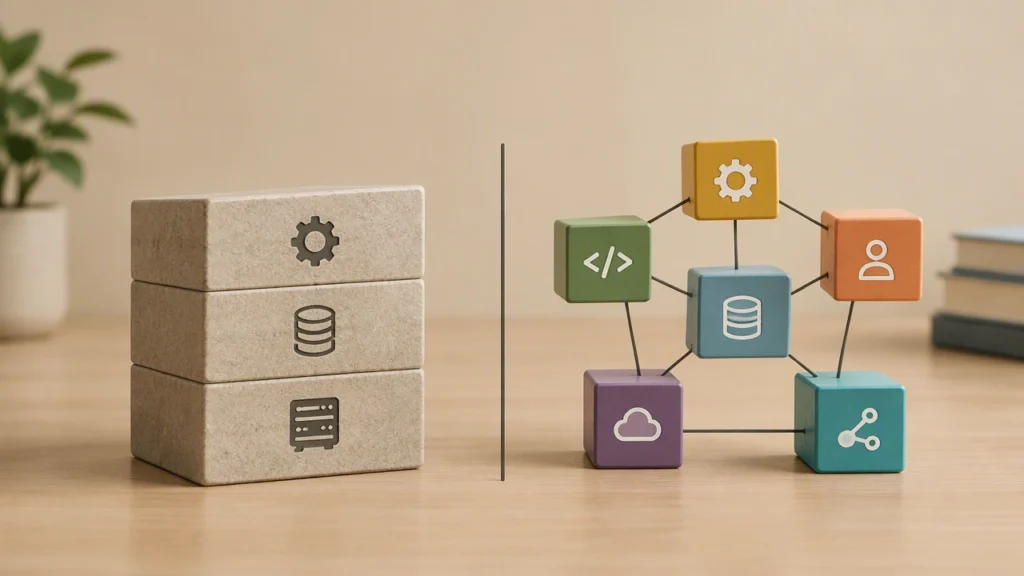
A monolith is a single deployable unit that contains all features. Modules may be well separated inside the codebase, but they ship together and share one process and one database. A microservice architecture splits the system into small services. Each service owns its own data, runs in its own process, and communicates over the network using APIs or events.
Why the choice matters for scale
Scale is not only requests per second. It also means the ability to grow the team, change features safely, and operate the system in production. The two styles affect latency, failure isolation, data consistency, deployment speed, and cost in different ways. Understanding these effects is the core of microservices vs monolith architecture pros and cons explained in practice.
Trade-offs that matter
Latency and performance
A monolith can call functions in memory, which is fast and simple. Microservices call each other over the network, which adds latency and serialization cost. In a monolith, cross-module logic is cheap. In microservices, you must design contracts, handle retries, and sometimes accept eventual consistency. For low-latency paths, fewer network hops usually win.
Fault isolation
In a monolith, a crash in one module can take down the whole process. In microservices, failures can be contained to one service. However, microservices introduce new failure modes like partial outages, slow dependencies, and cascading timeouts. Without good timeouts, retries, and circuit breakers, a small failure can still ripple through the system.
Data ownership and transactions
A monolith can use one database and run multi-table transactions easily. Microservices prefer database-per-service ownership to avoid tight coupling. This improves autonomy but makes cross-service transactions harder. Teams often use sagas, outbox patterns, or choreography to keep data consistent without distributed two-phase commits.
Deployment and release speed
A monolith has one artifact and one release pipeline. That makes rollbacks simple but can slow down teams that step on each other. Microservices allow independent deploys, feature rollouts, and canary releases per service. The trade-off is more pipelines, more versioning, and more coordination around API compatibility.
Team structure and autonomy
Monoliths work well when the team is small or when features are tightly coupled. Microservices shine when multiple teams need to ship independently. Each service can have its own backlog, on-call rotation, and release cadence. Conway’s Law matters here: your architecture often mirrors your communication structure.
Operational complexity
A monolith is simpler to run. Microservices need service discovery, configuration management, distributed tracing, centralized logs, and often a service mesh or API gateway. Observability becomes critical. Without it, debugging is slow and incidents are harder to contain.
Cost
Microservices can increase cloud spend because each service may need its own compute, memory, and databases. They also increase the cost of engineering tooling and on-call. Monoliths can be cheaper to run and staff at first, but they may become expensive to change as the codebase grows and release risk rises.
When a monolith is the better choice
- Early product stage: when requirements change fast and the team is small, a monolith reduces coordination overhead.
- Low-latency paths: when you need fast in-process calls and simple transactions.
- Simple operations: when you want fewer moving parts and lower cloud costs.
- Strong domain cohesion: when features are tightly coupled and benefit from shared models.
When microservices make more sense
- Multiple teams: when you need independent deploys and clear service ownership.
- Distinct scaling needs: when parts of the system have very different load patterns.
- Isolation requirements: when failure in one capability must not affect others.
- Technology diversity: when different services benefit from different runtimes or data stores.
A practical decision framework
1) Map the domain
Use domain-driven design to find boundaries. If two features share many entities and workflows, keep them together. If they change for different reasons, separate them.
2) Start with a modular monolith
Build clear module boundaries, strict APIs between modules, and separate schemas inside one database. This gives you the internal clarity of services without the network cost. If scaling or team autonomy becomes a bottleneck, extract services later.
3) Measure before splitting
Look at deploy frequency, lead time, failure rate, and change failure rate. Check which modules cause conflicts or performance hotspots. Split where the data shows pain, not where the blog post suggests.
4) Plan for data
Define who owns each dataset, how cross-service reads work, and how you will keep consistency. Choose simple patterns first, like outbox-based events or read-through APIs, before advanced choreography.
5) Invest in platform basics
If you go microservices, build or adopt foundations early: CI/CD per service, structured logging, tracing, health checks, and safe rollout strategies. Without these, microservices will slow you down.
Common mistakes to avoid
- Splitting too early: creating services before domain boundaries are stable increases rework.
- Splitting too late: waiting too long can lock you into a tangle of modules that are hard to separate.
- Shared databases: letting multiple services write to the same tables destroys autonomy and creates hidden coupling.
- Ignoring operability: adding services without tracing, metrics, and on-call processes makes incidents harder to resolve.
- Over-engineering resilience: adding retries and circuit breakers everywhere without budgets and timeouts can amplify failures.
A balanced path for scalable systems
Most teams benefit from a pragmatic path. Begin with a well-structured monolith, enforce module boundaries, and measure real bottlenecks. Extract services only where team autonomy, failure isolation, or scaling demands justify the extra complexity. Keep the number of services as low as possible while still meeting your goals.
This approach gives you the simplicity of a monolith where it helps and the flexibility of microservices where it matters. In practice, microservices vs monolith architecture pros and cons explained through clear metrics and domain boundaries leads to better decisions than following trends.
Key takeaways
- Choose based on evidence: use deploy speed, incident patterns, and scaling needs to guide splits.
- Protect data ownership: prefer clear boundaries and simple consistency patterns over shared databases.
- Invest in platform basics: observability, CI/CD, and safe releases are non-negotiable for microservices.
- Stay pragmatic: a modular monolith can carry you far, and selective extraction keeps complexity in check.